Multi-LLM RAG Assistant
One vector store, three model backends: ask the same grounded question to a local, a proprietary and a hosted open-source LLM.
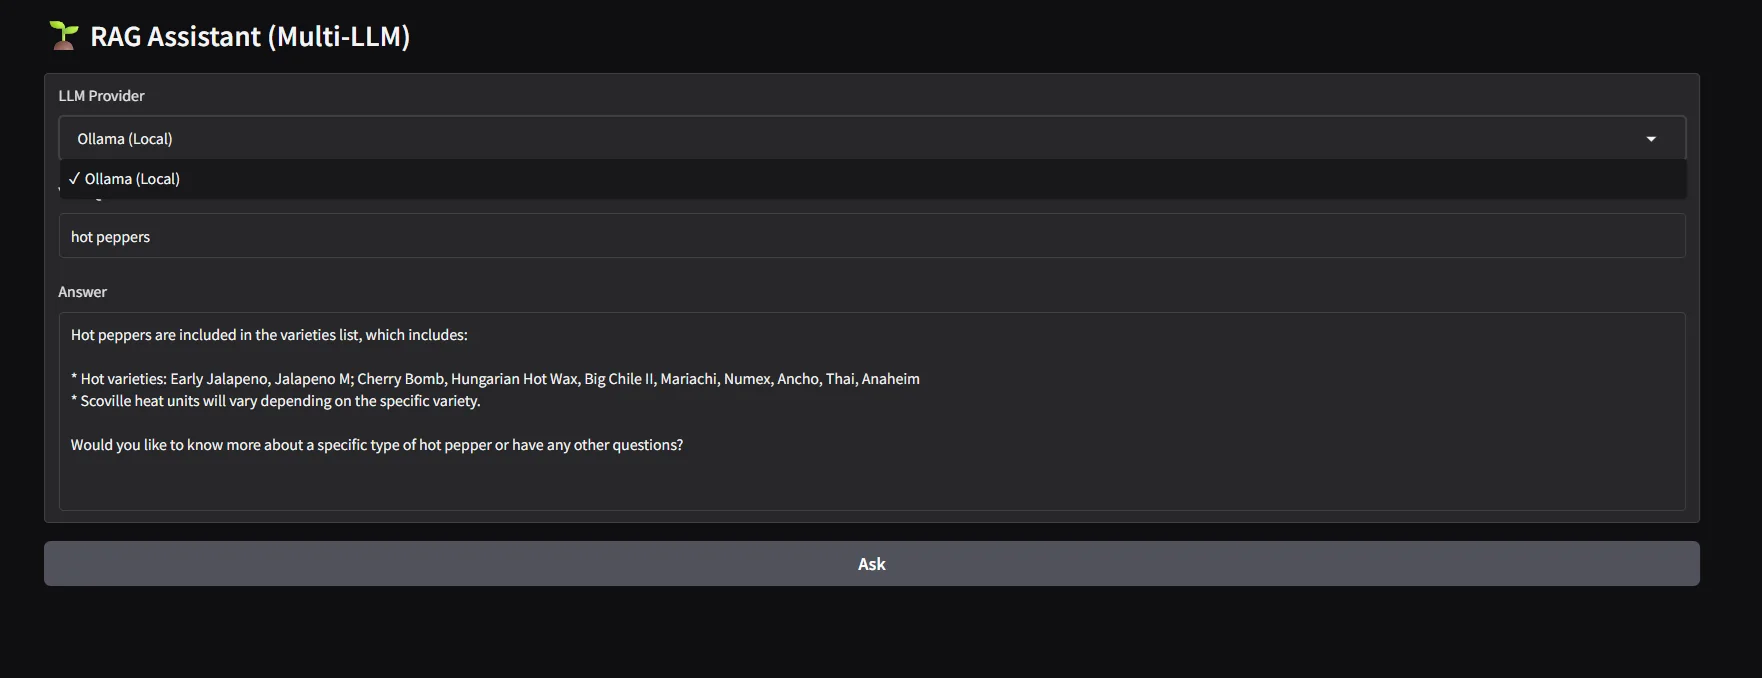
Overview
A PDF is chunked into ChromaDB once. A Gradio interface retrieves the top chunks for a question and sends the same prompt to the provider the user selects: Ollama (llama3.2), OpenAI (gpt-4o-mini) or Hugging Face Inference (Llama-3.1-8B-Instruct).
Problem
Which model should answer? Comparing local and cloud models is hard when each has its own retrieval setup, so the retrieval layer has to stay fixed while the model changes.
Architecture
- Ingestion scriptPDF loader → recursive splitter (350 / 100) → Chroma persistent collection.
- RetrieverChroma query returning the top 4 chunks.
- Prompt templateContext-only answering with a refusal when nothing is retrieved.
- Provider routerOne function per backend behind a single dispatch.
- Gradio UIProvider dropdown, question box, answer panel.
AI pipeline
- 01
Input
A question and a chosen provider.
- 02
Preprocessing
Documents were chunked at ingestion time.
- 03
Retrieval
Top-4 similarity search in ChromaDB.
- 04
LLM
The identical prompt goes to Ollama, OpenAI or Hugging Face.
- 05
Output
A grounded answer, or "I don't know" if nothing is retrieved.
- Dense retrieval with ChromaDB
- Prompt-level grounding with an "I don't know" fallback
- Runtime LLM provider routing
Engineering
- Retrieval fixed, model swappable
- Only the generation step changes between providers, which keeps comparisons honest.
- One function per provider
- Ollama streams over REST and is parsed line by line; OpenAI and Hugging Face use their SDKs. A small router picks one.
- Keys stay in the environment
- API keys are read from environment variables and nothing secret is committed.
Challenges
- No challenges are documented in the repository.
Results & limits
Measured
- No evaluation has been run and no answer-quality numbers exist.
Known limits
- Single source document, which is not included in the repo.
- Embeddings use Chroma's default function rather than a chosen model.
- No chat history, tests or evaluation set.
Stack
- Python
- ChromaDB
- LangChain loaders
- Gradio
- Ollama
- OpenAI API
- Hugging Face Inference
Source
Demo
No public demo for this one yet. The source repository has setup instructions.